
Incident metrics that matter
Mean time to recovery is the metric everyone quotes and the one most easily gamed. The useful numbers are the ones that decompose it.
Mean time to recovery is the metric everyone quotes and the one most easily gamed. The useful numbers are the ones that decompose it.
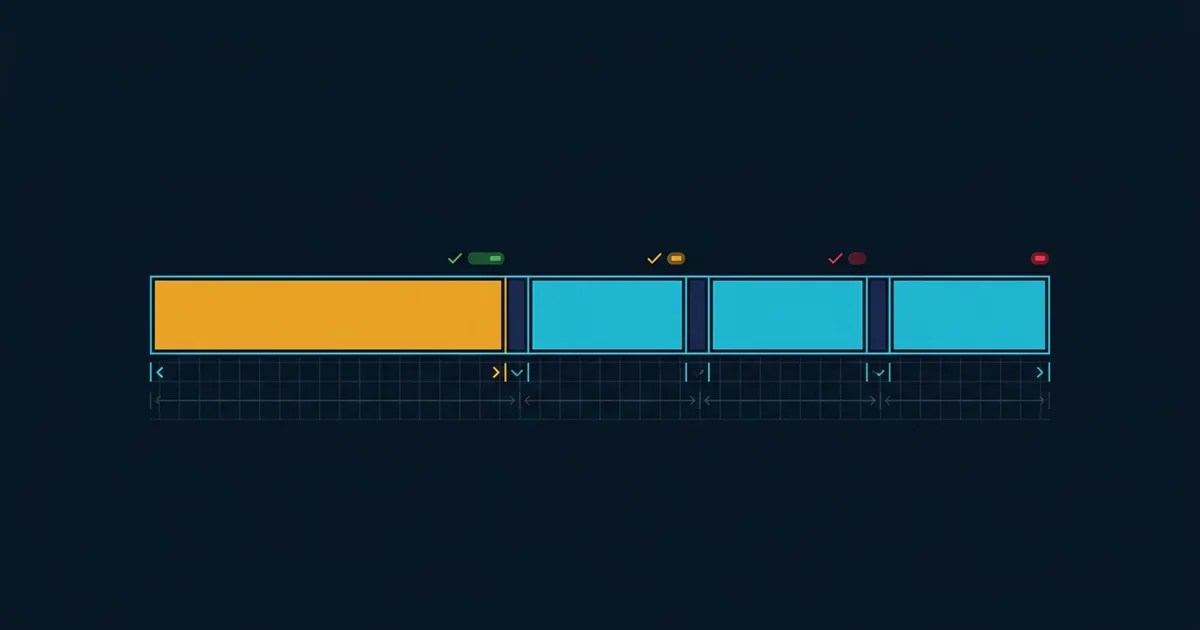
Incident metrics exist to answer two questions: Are we getting better, and where should we spend effort. Most teams track the one metric that answers neither.
Mean time to recovery is the average elapsed time from an incident starting to service being restored. It is the headline number, and on its own it tells you nothing actionable - Because it is a sum of four quite different phases.
| Metric | Measures | Improved by |
|---|---|---|
| MTTD - Detect | Start until someone knows | Better monitoring and alerting |
| MTTA - Acknowledge | Alert until a human engages | On-call rotation and escalation |
| MTTI - Investigate | Engagement until cause identified | Observability, runbooks |
| MTTR - Repair | Cause known until restored | Rollback tooling, automation |
The reason to split them is that teams consistently assume the problem is repair and it usually is not. A team with a four-hour MTTR that turns out to be three hours of detection has a monitoring problem, not an engineering one - And no amount of faster deploys will fix it.
Detection is also the cheapest phase to improve. A better health check costs an afternoon; halving repair time can be a quarter of work.
Incident durations are heavily skewed: A large number of short events and a small number of very long ones. A mean over that distribution is dominated by the tail.
Twenty incidents of five minutes and one of twelve hours gives a mean of about 39 minutes - A number that describes none of the twenty-one incidents. It is not the typical case and it is not the bad case.
Use the median for the typical incident and the 95th percentile for the bad one. Track both. A median that is stable while p95 grows means your worst incidents are getting worse, which is exactly the thing a mean would hide.
And count incidents by severity rather than aggregating everything. A metric that mixes a two-minute degradation with a four-hour outage is measuring two different phenomena.
Mean time between failures comes from hardware reliability, where components wear out on a distribution you can characterise and where the next failure is roughly independent of the last.
Software does not wear out. Failures are caused by changes, load and dependencies, which makes them correlated rather than independent: Incidents cluster after a big release, during a migration, or when a system is near capacity. A mean interval over that is not predictive of anything.
The useful replacement is change failure rate - The proportion of deploys that cause a degradation. That connects failures to their actual cause and is directly actionable: If a quarter of your deploys break something, the problem is the release process.
The most behaviour-changing metric on this page, because it turns reliability into a quantity you can spend.
If your objective is 99.9% availability, your error budget is 0.1% - About 43 minutes a month. Downtime consumes it. While budget remains, you ship features. When it is exhausted, you stop shipping and spend the time on reliability.
What makes this work is that it removes an argument. Instead of a recurring negotiation between product and engineering about whether to prioritise reliability, there is a number, and the number decides. It also legitimises spending the budget: If you have used none of it, you are being too conservative and could be moving faster.
Number of incidents, on its own. A team that declares an incident for every degradation looks worse than one that only declares for total outages, while being better run. The definition drives the number.
Uptime percentage for a short period. "100% this month" is true of most services most months.
Anything used to compare teams. Metrics used for evaluation get optimised, and incident metrics are unusually easy to optimise the wrong way: Declare fewer incidents, close them earlier, classify them lower. Every one of those improves the number and makes the organisation worse.
The failure mode to watch for: A team whose MTTR improves while customer complaints do not. That usually means incidents are being closed when the fix is deployed rather than when service is actually restored - And recovery is not the same as the fix.
For most teams, five numbers are enough:
Review them monthly, look for trends rather than single points, and never use them to rank people.
Mean time to recovery: The average elapsed time from an incident starting to service being restored. On its own it is not actionable, because it combines detection, acknowledgement, investigation and repair - Four phases that are improved in completely different ways.
Because incident durations are heavily skewed: Many short events and a few very long ones. The mean is dominated by the tail and describes none of the actual incidents. Track the median for the typical case and the 95th percentile for the bad case.
Not really. Mean time between failures assumes independent failures from components that wear out, which is a hardware model. Software failures are caused by changes, load and dependencies, and they cluster. Change failure rate is the useful replacement.
The amount of downtime your availability objective permits - 0.1% for a 99.9% target, about 43 minutes a month. While budget remains you ship features; when it is exhausted you stop and spend the time on reliability. It replaces an argument with a number.
The uptime nines table, what each level costs to achieve, and why how uptime is measured matters more than the number itself.
Why too many alerts is more dangerous than too few, and how to design alerting that people still respond to after six months.
Typical outage durations by cause, why most incidents resolve in minutes, and the warning signs that an outage is going to be a long one.
What service level agreements really commit a provider to, how credits are calculated and claimed, and the exclusions that matter most.